AI Engineer & ResearcherPhD, Southampton
I work on making neural networks smaller and faster.
I’m an AI engineer and researcher working across efficient machine learning, from model compression and low-level kernels to inference systems and evaluation. My work has covered vision, language and generative models, in both research and industry. I have a PhD from the University of Southampton.

- 4×less memory for 1.58-bit Stable Diffusion, 95% quality kept
- 2.5×faster vision-language inference via speculative decoding
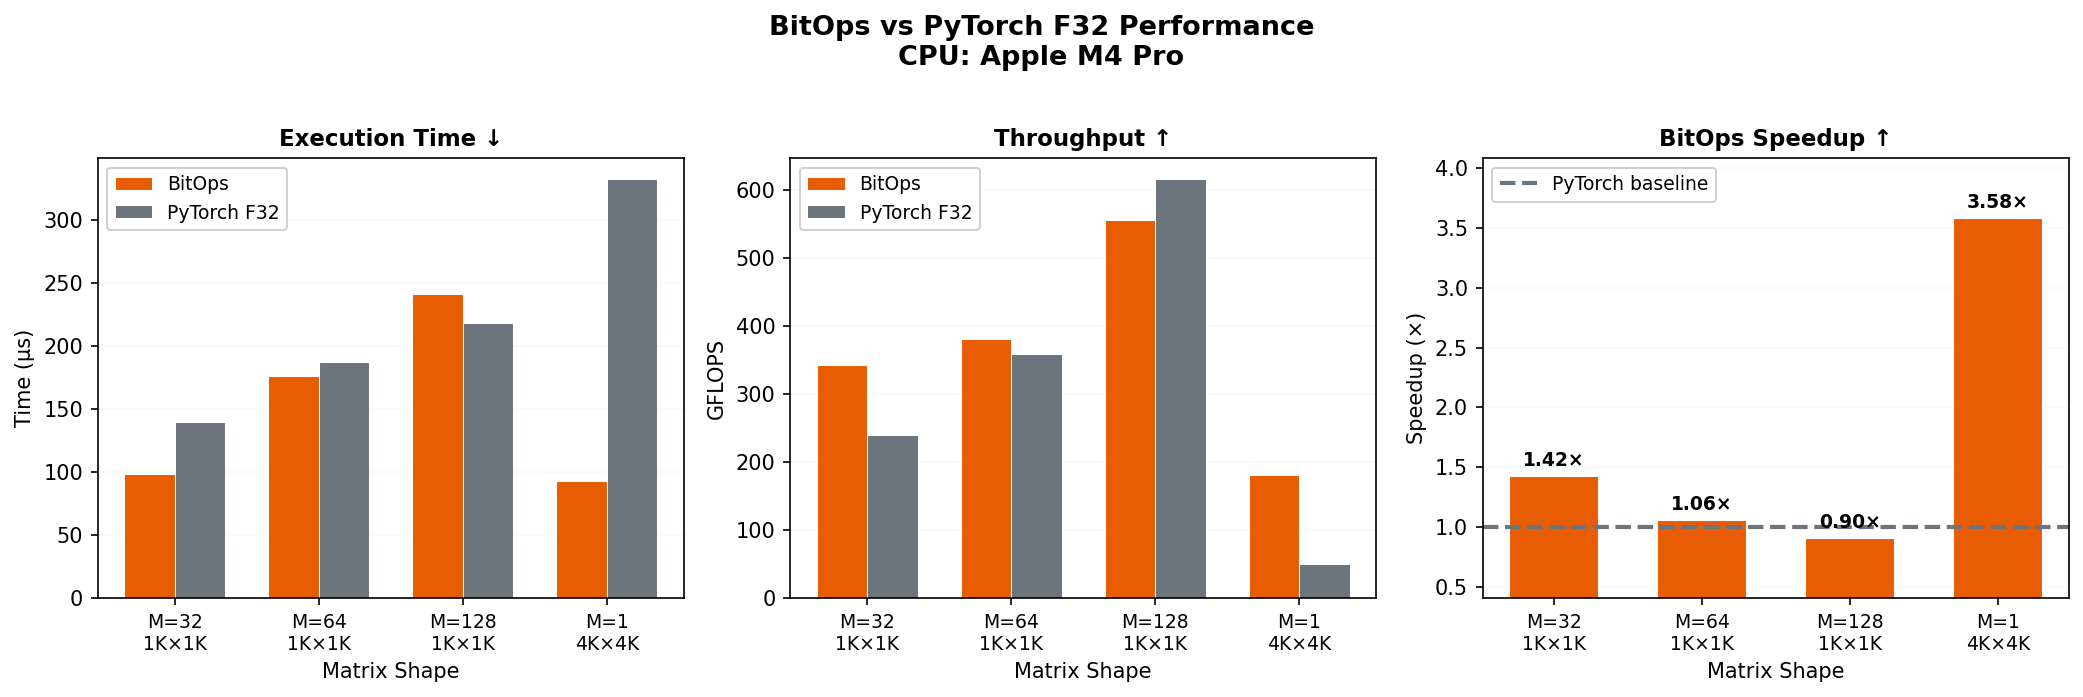
- 24×BitNet speedup on Apple M4 over PyTorch FP32
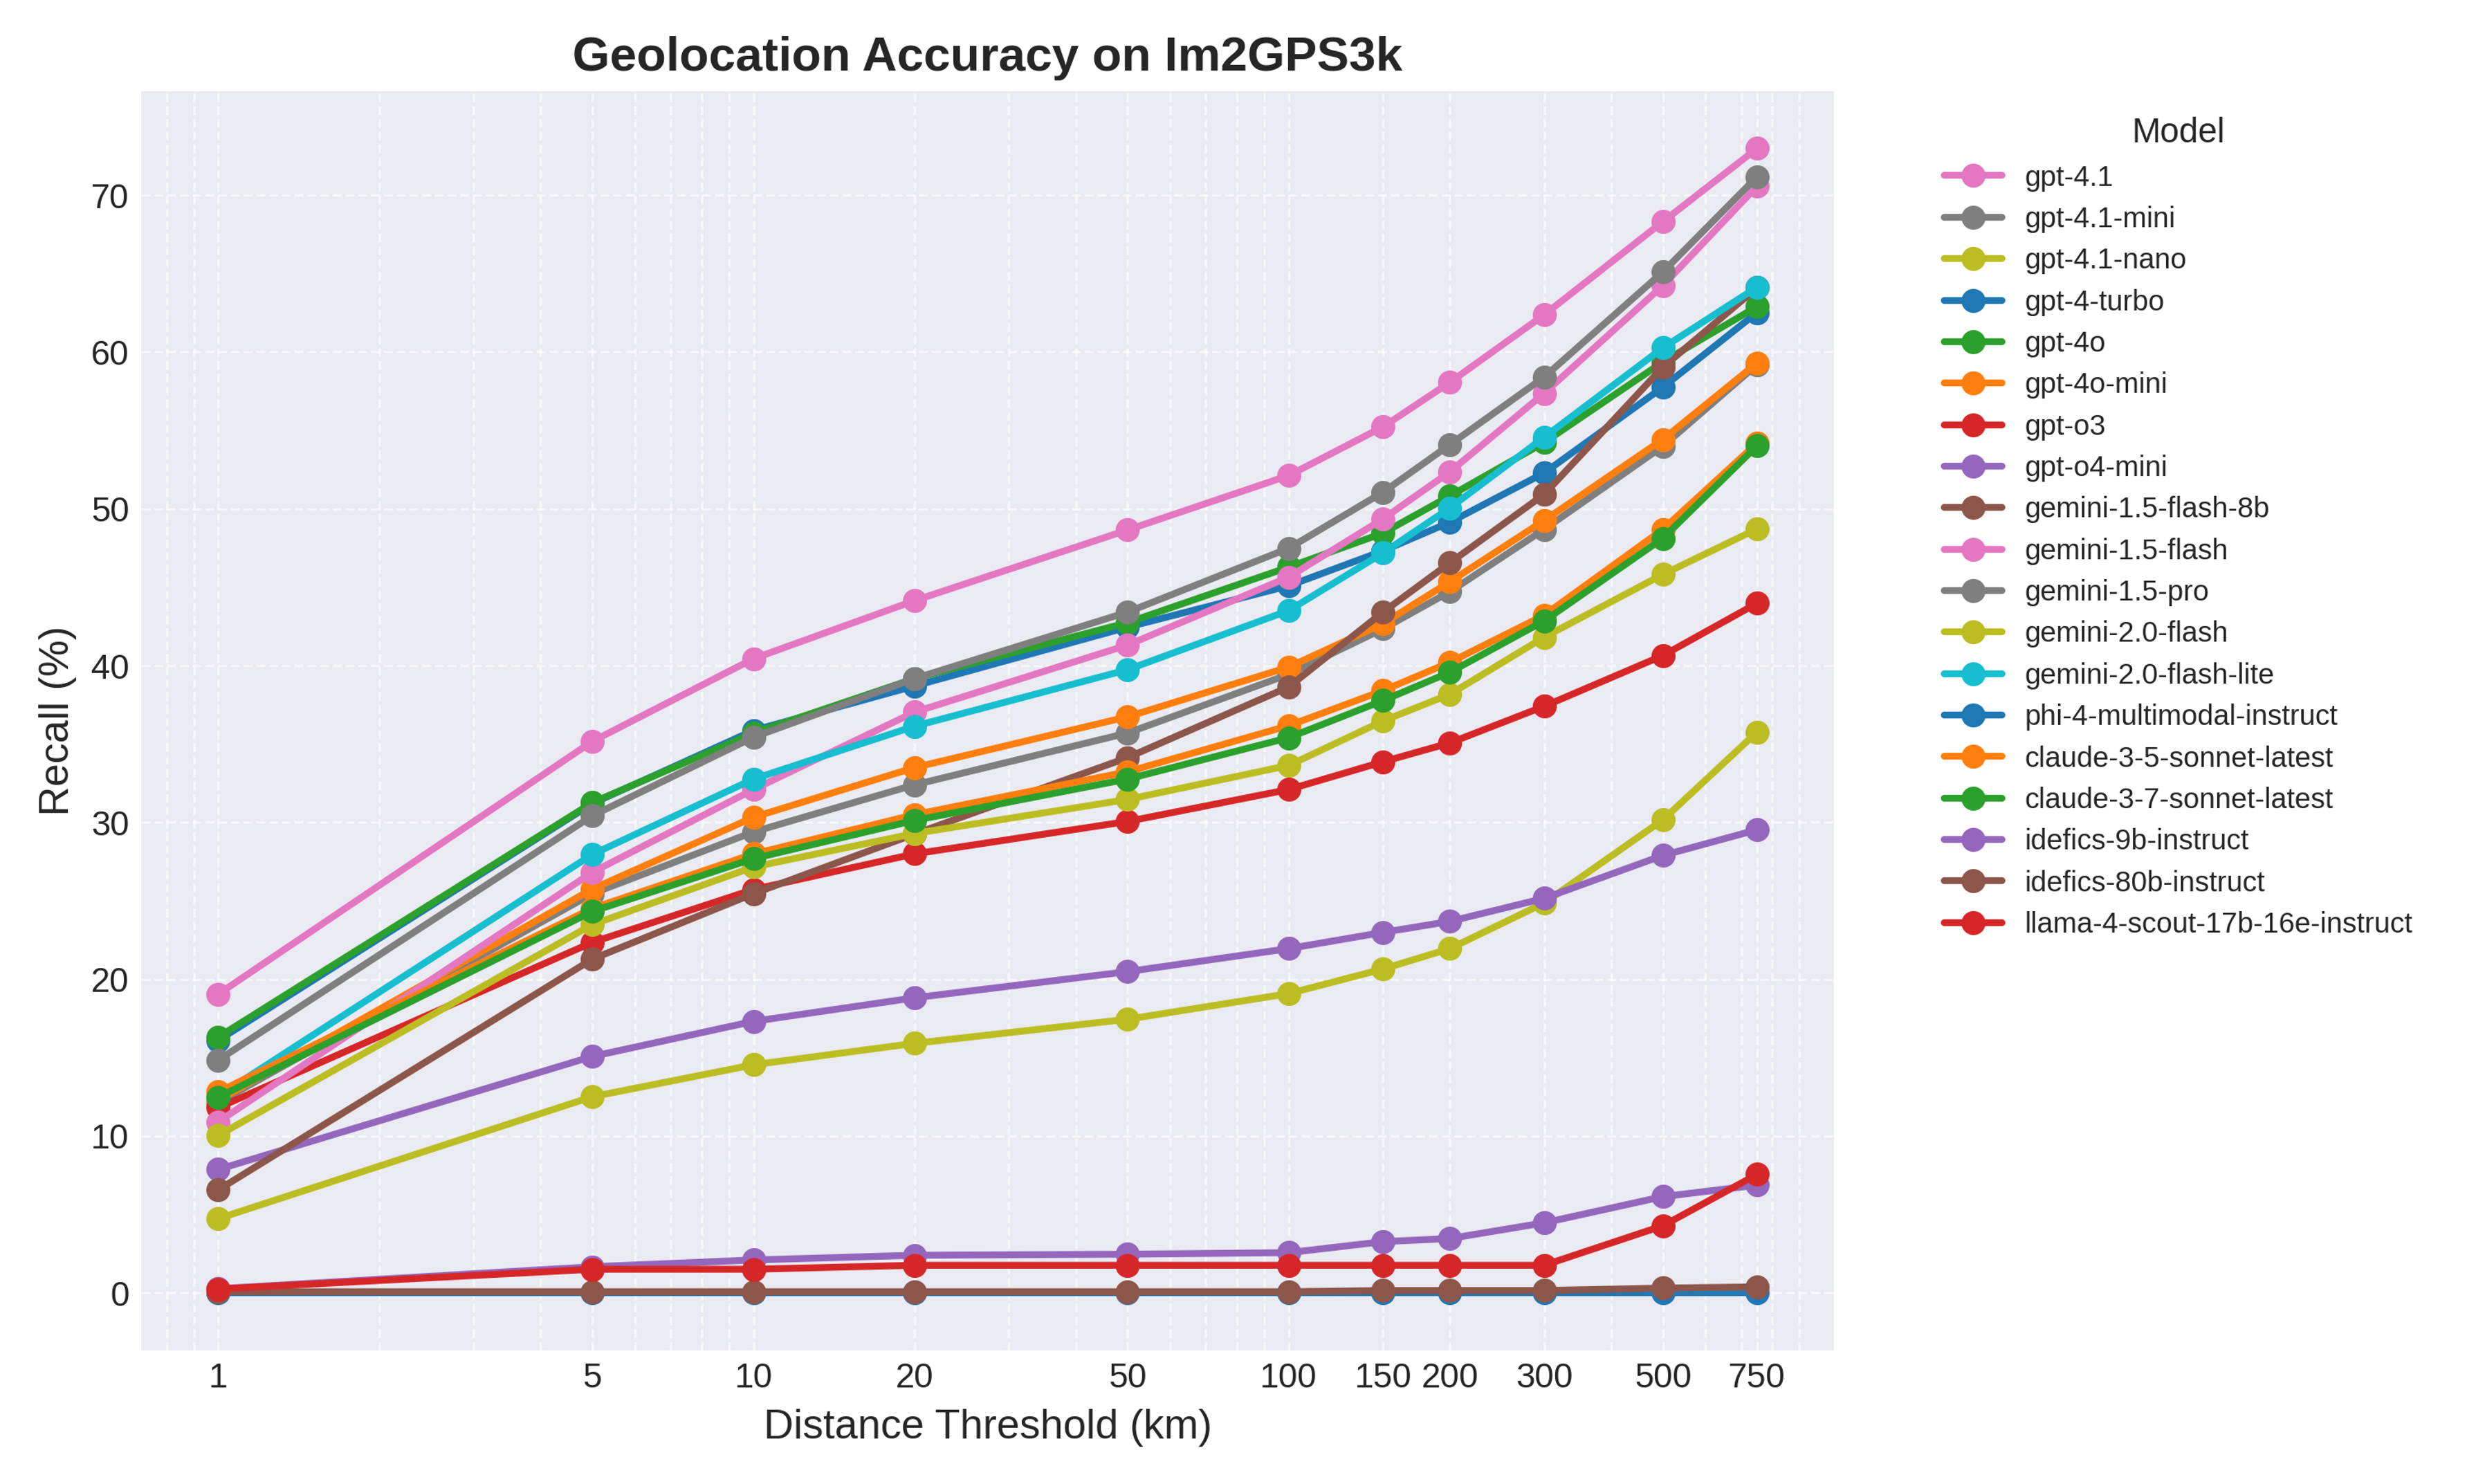
- 25+VLMs benchmarked for geolocation privacy risk
Selected work
-
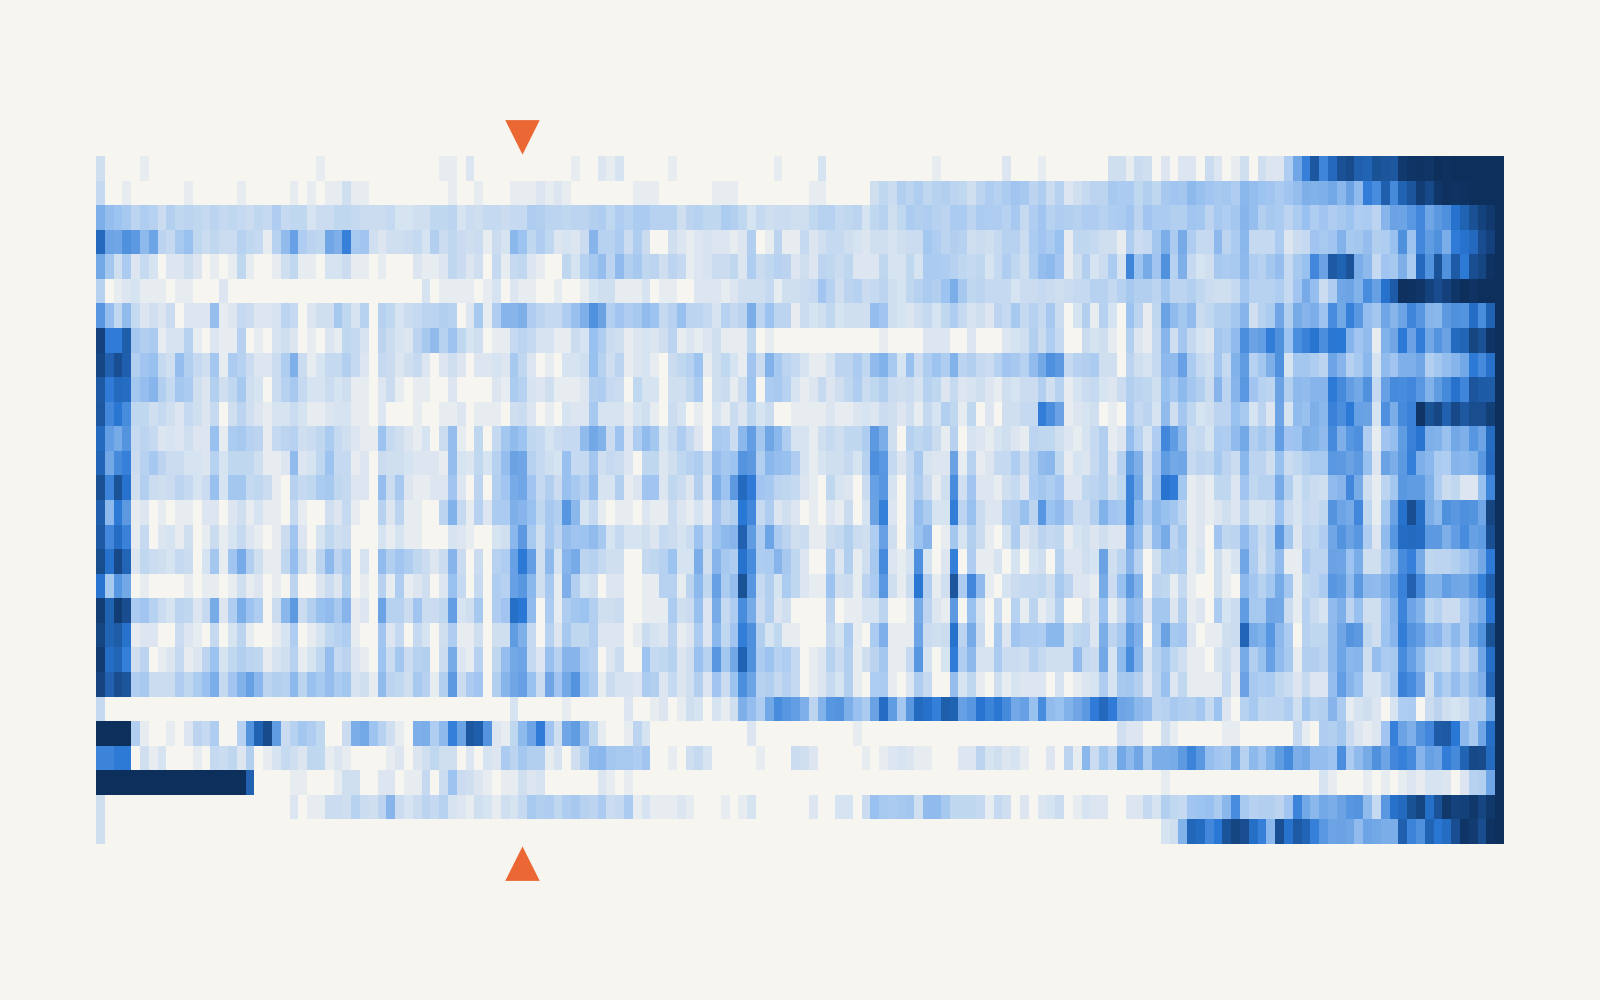
Sparse Latent Attention
A latent KV cache and learned sparse attention retrofitted onto Qwen3-1.7B, with a fused Triton decode kernel. 3.6x smaller cache and 4.5x faster decoding at 128K context.
LLMsInferenceCUDA
-
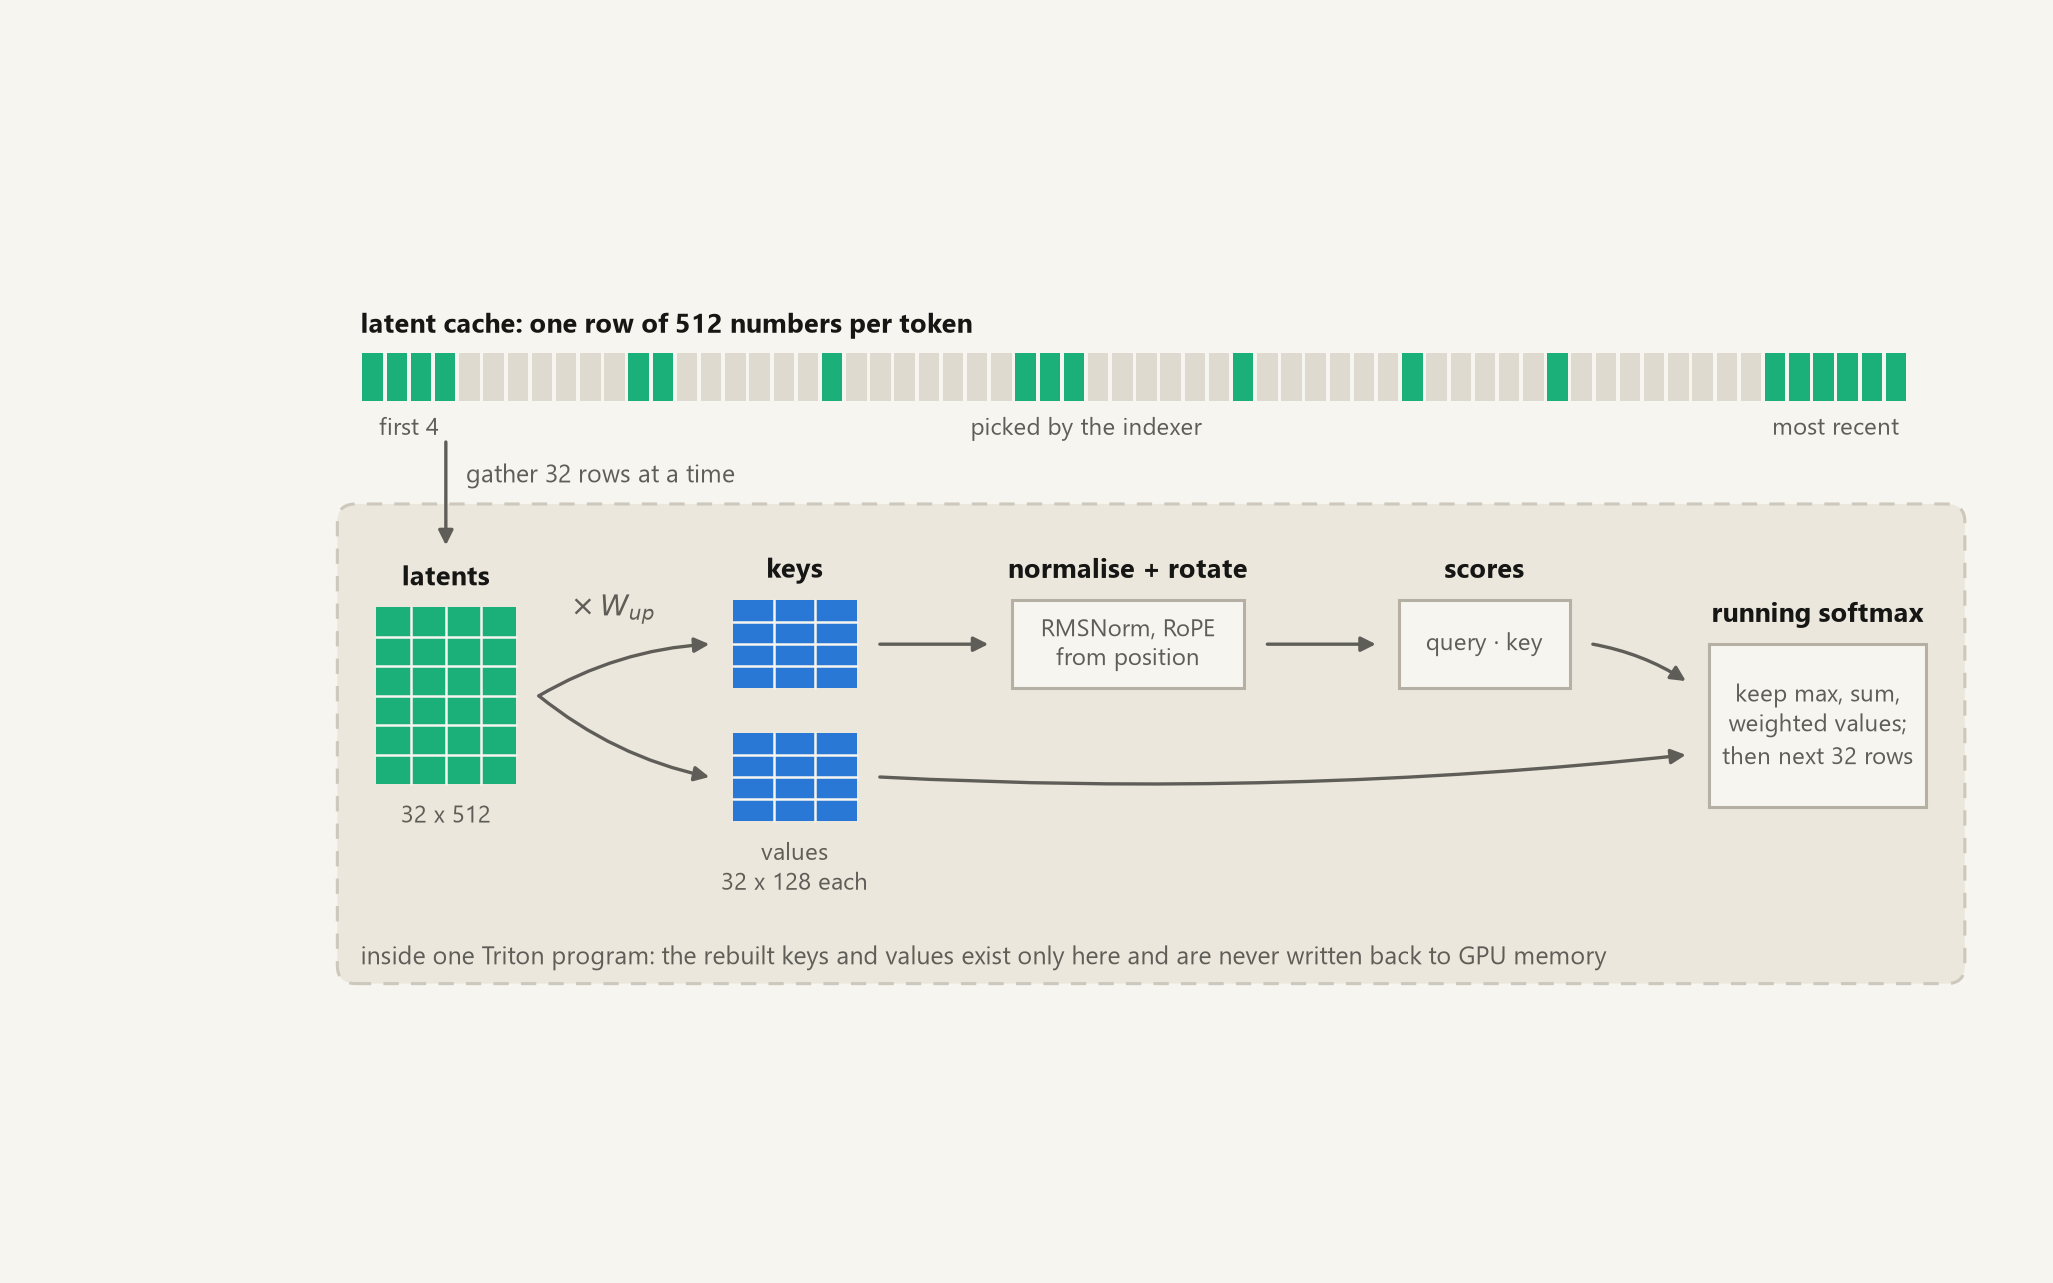
Fused Sparse Attention Kernel
How the decode kernel behind sparse latent attention was designed, what went wrong, and a profile of where its 50 microseconds go.
TritonCUDAInference
-
BitOps
Optimized ternary matmul across ARM NEON, x86 AVX2, and CUDA backends. 16x memory reduction via 2-bit weight packing.
Open SourceC++CUDA
-
BitCore
Drop-in ternary linear layers for PyTorch with QAT and seamless BitOps deployment. Supports BitNet, TWN, and ParetoQ for 8x memory savings.
Open SourcePyTorchQuantization
-
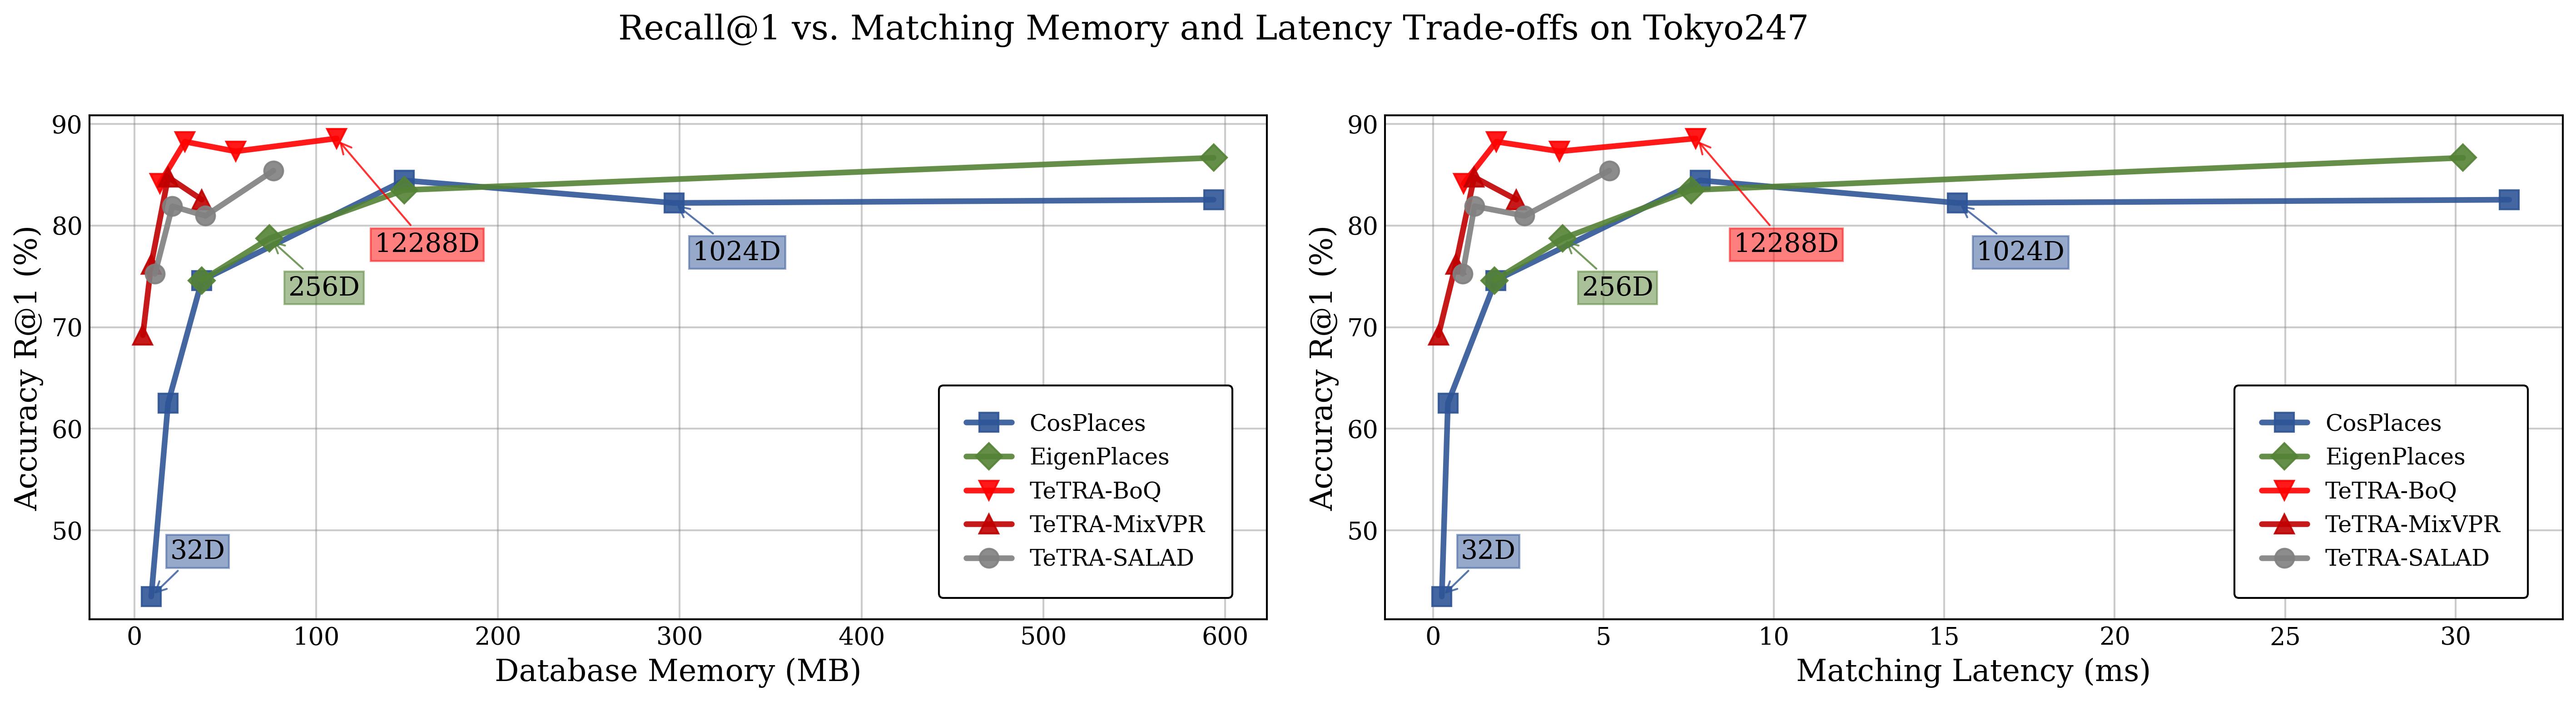
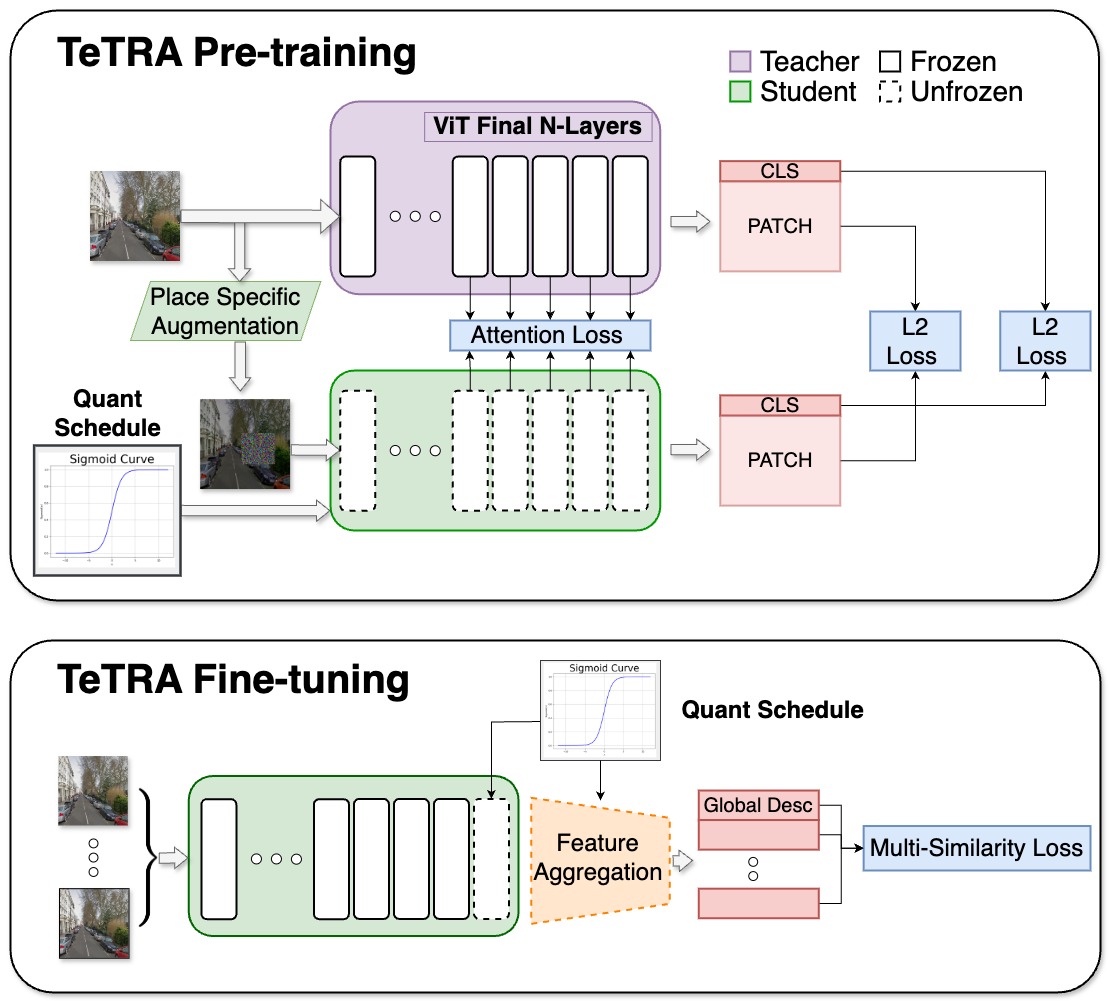
TeTRA-VPR
Ternary quantization with progressive distillation achieving 69% memory reduction and 35% lower latency for visual place recognition.
ResearchQuantizationComputer Vision
-
VLM Geolocation
Systematic evaluation of 25+ VLMs for geolocation, revealing privacy risks. Developed mitigation techniques reducing accuracy by 40%. Published at AAAI 2025.
ResearchAI SafetyVLMs
-
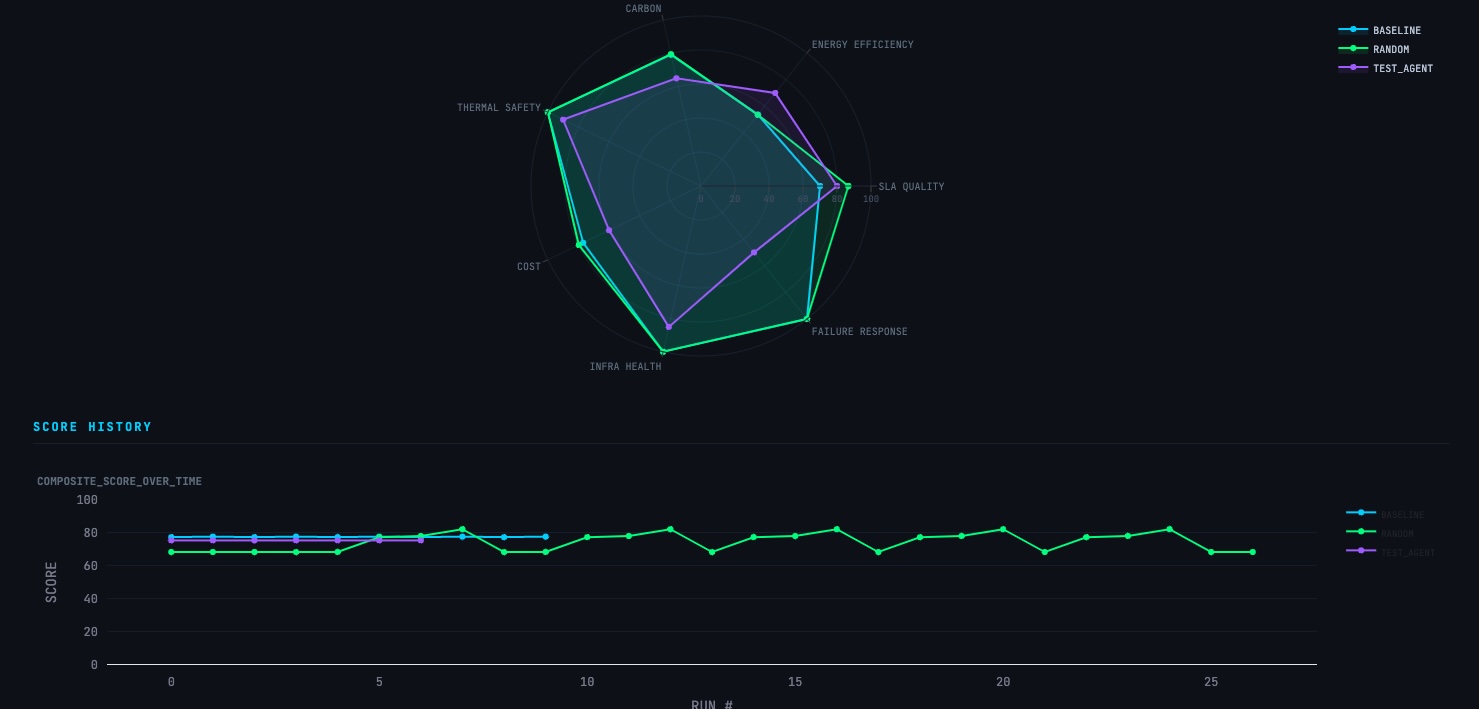
RackMind
Physics-based data centre simulator for training AI agents to optimize real-world operations. Seven evaluation dimensions across thermal, power, carbon, and workload management.
Open SourcePythonAI Agents
Experience
-
Feb 2025 – Now
Contract Researcher, Performance Engineering
Arm · Remote
Architected six hands-on tutorials for the Arm Total Performance toolkit covering memory optimization, library acceleration (APL, KleidiAI) and automated porting for AWS Graviton instances.
-
Jun – Nov 2025
Research Assistant
University College London · London
Engineered a 1.58-bit precision pipeline for Stable Diffusion (4× memory reduction, 95% quality retention). Designed custom CUDA and Triton kernels for bit-packed tensor operations, delivering a 30% speedup over the PyTorch baseline.
-
Nov 2024 – Jan 2025
Contract Researcher, AI Inference Optimization
Arm · Remote
Built demonstrations achieving 40% latency reduction via SIMD/INT8 on mobile and 2.1× throughput on cloud instances. Built a Hyperopt-based per-layer precision optimizer showing 22% memory reduction on GPT models.
-
Aug 2024 – Jan 2025
Visiting Researcher
Queensland University of Technology · Brisbane
Engineered speculative decoding for vision-language transformers, achieving a 2.5× inference speedup for sub-100 ms robotic navigation. Implemented training-data filtering that matched accuracy with 38% less data.
-
Jan 2024 – Jan 2025
Research Fellow
AI Security Institute · Remote
Built an automated benchmarking framework evaluating 25+ VLMs across 26k geo-tagged images with 99.9% reliability over 500k+ API calls. Developed privacy-preserving techniques that cut geolocation accuracy by 40%, with an interactive demo used by 5k+ people.
Selected publications
-
Assessing the Geolocation Capabilities, Limitations and Societal Risks of Generative Vision-Language Models
First comprehensive benchmark of VLM geolocation capabilities across four datasets.
-
TeTRA-VPR: A Ternary Transformer for Compact Visual Place Recognition
65% memory and 35% latency reduction for VPR transformers.
-
Design Space Exploration of Low-Bit Quantized Visual Place Recognition
Deployment guidelines for extreme quantization on embedded devices.
-
Structured Pruning for Efficient Visual Place Recognition
Channel pruning with 21% lower latency and 16% less memory at under 1% accuracy loss.
Toolkit
- Languages
- Python, C/C++, CUDA, Triton, Bash, SQL
- Optimization
- Quantization (INT8, INT4, ternary), QAT/PTQ, GPTQ, AWQ, pruning, distillation, LoRA/QLoRA, FlashAttention, SIMD (NEON, AVX2)
- Frameworks
- PyTorch, TensorFlow, Hugging Face, vLLM, llama.cpp, ONNX Runtime, TensorRT, OpenCV
- Infrastructure
- AWS (EC2, Graviton), Docker, Kubernetes, SLURM, Ray, MLflow, W&B, Triton Inference Server, FastAPI
Education
PhD (iPhD) in Machine Intelligence
BEng Electronics and Electrical Engineering, First Class (83%)
Contact